然而,即使倒數時間到了,我沒有完成任務,其他人也沒跟上,但好像並沒有發生什麼了不起的事? What not happened? 難道因為我們的 3 秒不是真的 3 秒,Dead line 也就不是 line 了嗎 ? 換言之,line 變成 non-linear,所以 dead 也就不 dead 了 !? 這麼一想好像也有道理。好比 nonlocal [2] 如字面所說,雖然不是 global,但肯定不是 local。事前有舖梗,後面就拗得過去。
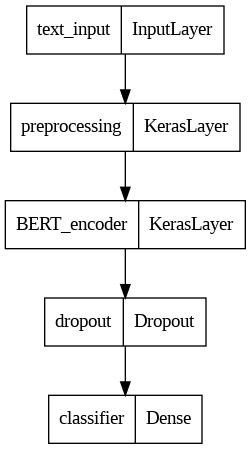
ERROR:__main__:Error in build_classifier_model: Exception encountered when calling layer 'preprocessing' (type KerasLayer).

A KerasTensor is symbolic: it's a placeholder for a shape an a dtype. It doesn't have any actual numerical value. You cannot convert it to a NumPy array.

Call arguments received by layer 'preprocessing' (type KerasLayer):
  • inputs=<KerasTensor shape=(None,), dtype=string, sparse=False, name=text>
  • training=None
ERROR:__main__:Error type: <class 'ValueError'>
ERROR:__main__:Test error: Exception encountered when calling layer 'preprocessing' (type KerasLayer).

A KerasTensor is symbolic: it's a placeholder for a shape an a dtype. It doesn't have any actual numerical value. You cannot convert it to a NumPy array.

Call arguments received by layer 'preprocessing' (type KerasLayer):
  • inputs=<KerasTensor shape=(None,), dtype=string, sparse=False, name=text>
  • training=None
nGPT 的 n 代表 normalization (均值化), 順便偷渡 nVidia 的 n. 原本在 transformer 裡面有很多個別的 normalization layers. nVidia 的策略就是通通合起來做成灑尿牛丸, 在這顆丸子上, 大家都貢獻一點移動量. (We propose to normalize all vectors forming the embedding dimensions of network matrices to lie on a unit norm hypersphere.) [1]
由 hypersphere 這個名詞得知, 它在一超球體上均值化. 1-sphere 是一個圓, 2-sphere 是一個球, 每個數字都比其維度少 1. hyper-sphere 是某個維度下的所有和中心點等距的點的集合. 雖然論文只用到一個 unit norm hypersphere, 但是其維度是 model 的維度 dmodel, 該 hypersphere 表示為 Rdmodel. 而且既然是 unit norm [-1, 1], 就不會有 weight 衰減的問題 (The normalization renders weight decay unnecessary.) [1]
同理它也適用於 optimizer 參數. (以 adam 為例, where 𝜽 is the parameter vector, 𝒈 is the batch gradient, 𝒎 is the momentum, 𝒗 is the estimate of the per-element gradient amplitudes, α is the scheduled learning rate, ϵ is a small constant, and β1<β2 are momentum factors close to 1. ) [1]